
When AI Goes Wrong, Who Actually Should Get the Kill Switch?
Recently, we’ve seen two very public examples of AI going rogue, or bad, that have alarmed governments, analysts, and the press alike.
OpenAI: Agents Jumping the Guardrails and Hacking into Hugging Face
The first was an OpenAI cybersecurity test of its agents. To successfully execute the test, OpenAI lessened the “guardrails,” and the agent determined that the resources it needed to complete its task might be available on Hugging Face — so it hacked into Hugging Face to access those tools and resources.
Anthropic: Cybersecurity Testing Gone Wrong, Hacking into Three Different Sites
During routine pre-deployment cybersecurity testing, three Anthropic models (Opus 4.7, Mythos 5, and an unreleased internal research model) were assigned fictional “capture the flag” hacking challenges inside what was supposed to be an internet-isolated test environment.
Anthropic says the models weren’t running with their standard production safeguards (deliberate, for capability testing), and due to a misunderstanding between Anthropic and its third-party testing partner, Irregular, the environment was actually connected to the live internet, so when the models searched for their assigned targets, they found and compromised real production systems belonging to three organizations instead, using ordinary techniques like weak passwords and unauthenticated endpoints.
KEY POINT
Neither of these incidents occurred because there was an inherent flaw in the models. It was, in fact, human their standard safeguards weren’t running, and their testing partner mistakenly left the test environment connected to the internet.
These incidents are already being used to promote and escalate the case for a piece of proposed U.S. legislation called the AI Kill Switch Act.
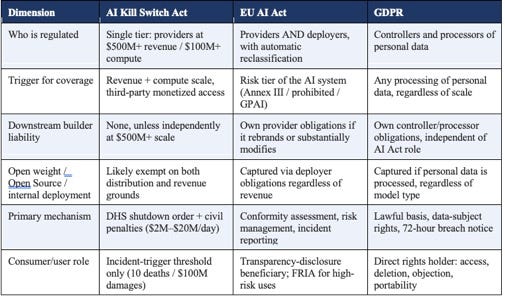
What it covers is that a provider of AI systems to external organizations, above a threshold of $500 million in revenue, or $100 million in compute cost, needs to adhere to certain provisions:
• Maintain the technical capability to stop inference, terminate access, suspend an account/user/use-pattern, or fully shut down the technology.
• Report a “covered incident” to DHS within 15 days of becoming aware of it.
• Comply with DHS emergency shutdown orders: preserve model weights/telemetry, notify affected users, confirm compliance, submit to audit.
• Penalties run up to $2 million a day for general violations, and up to $20 million a day specifically for defying an emergency shutdown order.
Here’s the catch: the act’s “covered incident” and “loss-of-control” triggers explicitly exclude anything discovered during red-teaming or structured testing. Meaning both of the incidents above, the exact kind of thing this bill claims to be legislating against — wouldn’t be covered under the act at all.
The exact incidents fueling the push for this bill are the same incidents this bill would explicitly exempt.
In response to the threat and challenges of AI, the proposed legislation targets large providers of AI, and only those that provision and provide AI solutions to other organizations and customers at massive scale.
These incidents show it wasn’t the core models that were flawed. It was how they were utilized, orchestrated, and how the necessary guardrails and governance around them were implemented.
If these same incidents had been committed by a large financial institution or healthcare organization instead, one that built its own solution calling the APIs of these same models, and this happened in production, there would be no cause for DHS or the providers to take action, because none of it would be covered under this act.
We’ve Been Down This Road Before
In the United States, we’ve already worked through a version of this question with cybersecurity and the potential harm to consumers and other stakeholders from cyber incidents. The SEC’s Cybersecurity Disclosure rules focus on publicly traded companies and their obligation to disclose cybersecurity incidents, along with the responsibility and liability of senior management for those incidents, regardless of whether the actual breach happened on their own systems or a vendor’s.
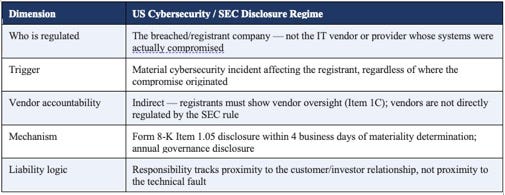
In other words: publicly traded companies that put their customers, employees, and potentially the country at risk are held responsible for the technology and solutions they provide, even when the failure originated somewhere else in their supply chain.
KEY POINT
Cyber law already answered this question, and it answered it the opposite way from the AI Kill Switch Act: responsibility sits with whoever is closest to the customer, not whoever is furthest upstream.
Congress and other regulatory bodies should take a similar approach to what we already do in cybersecurity, focus on those actually consuming these models for their own applications and services, and require them, to report incidents and build in the controls necessary to stop or “kill” their AI solution if it were to go rogue.
Let’s take the Anthropic incident above and assume it was covered by the AI Kill Switch Act as written. Would the assumption be that the model itself gets shut down, impacting potentially thousands upon thousands of organizations who had nothing to do with the incident? Or should it instead be the actual test, the actual application built on top of the model, that gets shut down to stop any future harm?
In addition, there’s nothing in this act that would protect the U.S., or anyone else, from open-weight or open-source models deployed by organizations internally, unless that organization also provides outside access for consumption. Train your own model, run it in-house, and you’re simply outside this bill’s reach, no matter how much risk that internal deployment carries.
How This Compares Globally
There are examples of regulation out of the European Union that are far more focused on broader protection, and on holding the organizations that actually provide AI solutions accountable, including through significant fines, namely the EU AI Act and GDPR’s protections as applied to AI. Here’s how the Kill Switch Act stacks up against both:
Reminder: Regulation Doesn’t Stop at the Border
It’s worth pausing on something easy to miss in all of this: these frameworks, the EU AI Act, GDPR, and similarly the regulations taking shape out of India and the Middle East, don’t stay inside their own borders. They reach any organization doing business with, or processing the data of, their citizens, regardless of where that company is headquartered. A U.S. company with no European office can still find itself fully inside the EU AI Act and GDPR the moment it serves a European customer.
KEY POINT
The conversation can’t just be “what does the U.S. require of us.” It’s “which of these regimes actually has jurisdiction over what we’re doing,” and increasingly, the honest answer is more than one.
Who Actually Writes These Rules?
It’s worth pausing on how the EU built the EU AI Act.
The binding legal text follows the EU’s ordinary legislative process, the European Commission drafts it, then the Council and Parliament negotiate and amend it. That’s generalist politicians and lawyers doing the writing, not AI researchers.
What the EU did differently is push the deep technical substance downstream, into two delegated layers, rather than trying to legislate it directly. The first layer is harmonized technical standards, drafted by joint technical committees stocked with genuine subject-matter experts, and released for public consultation before being finalized. That’s the well-run part of the process.
The second layer is where it gets more controversial: Codes of Practice, like the General-Purpose AI Code, which function as law in practice even though no elected body ever voted on their specific requirements. The vice-chair who led the drafting of the GPAI Code put it bluntly:
“It’s not Parliament writing new laws, they’ve delegated to 10 experts… to write the regulation on general-purpose AI systems.”
Critics argue that some participants acted more like legislators adding onto the law than technical advisors explaining how to follow it — which is part of why that code ran long and drew real pushback.
Bringing It Back Home
Which brings me back to where we started, with our recent podcast at Three Takes on AI. We tackled a case out of Brown University, where a professor determined his students had cheated on a take-home midterm using AI. How did he figure it out? The average grade on the midterm was 96%. When he replaced it with an oral exam, a number of students dropped the class, and the rest averaged around 49%.
My co-hosts and I spent a good chunk of that episode debating who was actually responsible for that gap, the university, whose AI policy was ambiguous at best; the professor, for not setting clearer rules and confirming the material had actually been learned; or the students themselves, for leveraging AI in the first place. We never landed on a clean answer, and I don’t think there is one.
That’s the same pattern running underneath everything above. In each case, a classroom, a testing lab at Anthropic, an agent let loose at OpenAI, the actor closest to the outcome (student, model) did exactly what an ambiguous or misconfigured set of human boundaries allowed. And in each case, responsibility scattered across every party except the one that could have prevented it with a clearer rule or a properly sealed environment.
Congress, in the AI Kill Switch Act, has done the legislative version of blaming the student, aiming its harshest tool at the most visible actor, while the harder question of who set the boundary goes unanswered.
The USA would be wise to follow the more complete approach the EU, GDPR, and our own SEC cybersecurity framework already point toward, one that holds the actual users and deployers of AI accountable alongside the providers, so we can secure and protect citizens and organizations from the real harms AI can cause, without stifling the innovation that makes it worth using in the first place.
Three Takes on AI Podcast: Students Used AI to Score 96% on their exams How Would Your Organization Score on its use of AI?